One AI Model or a Router? A Creative Team’s Guide
Introduction
The most capable AI model is not automatically the best foundation for a creative workflow. Marketing teams need more than impressive one-off outputs: they need repeatability, brand control, reasonable costs, dependable turnaround times, and a process people can understand.
That creates a deceptively difficult choice. Should every brief, draft, revision, and quality check pass through one general-purpose model? Or should an AI router inspect each request and send it to the model judged best for that task?
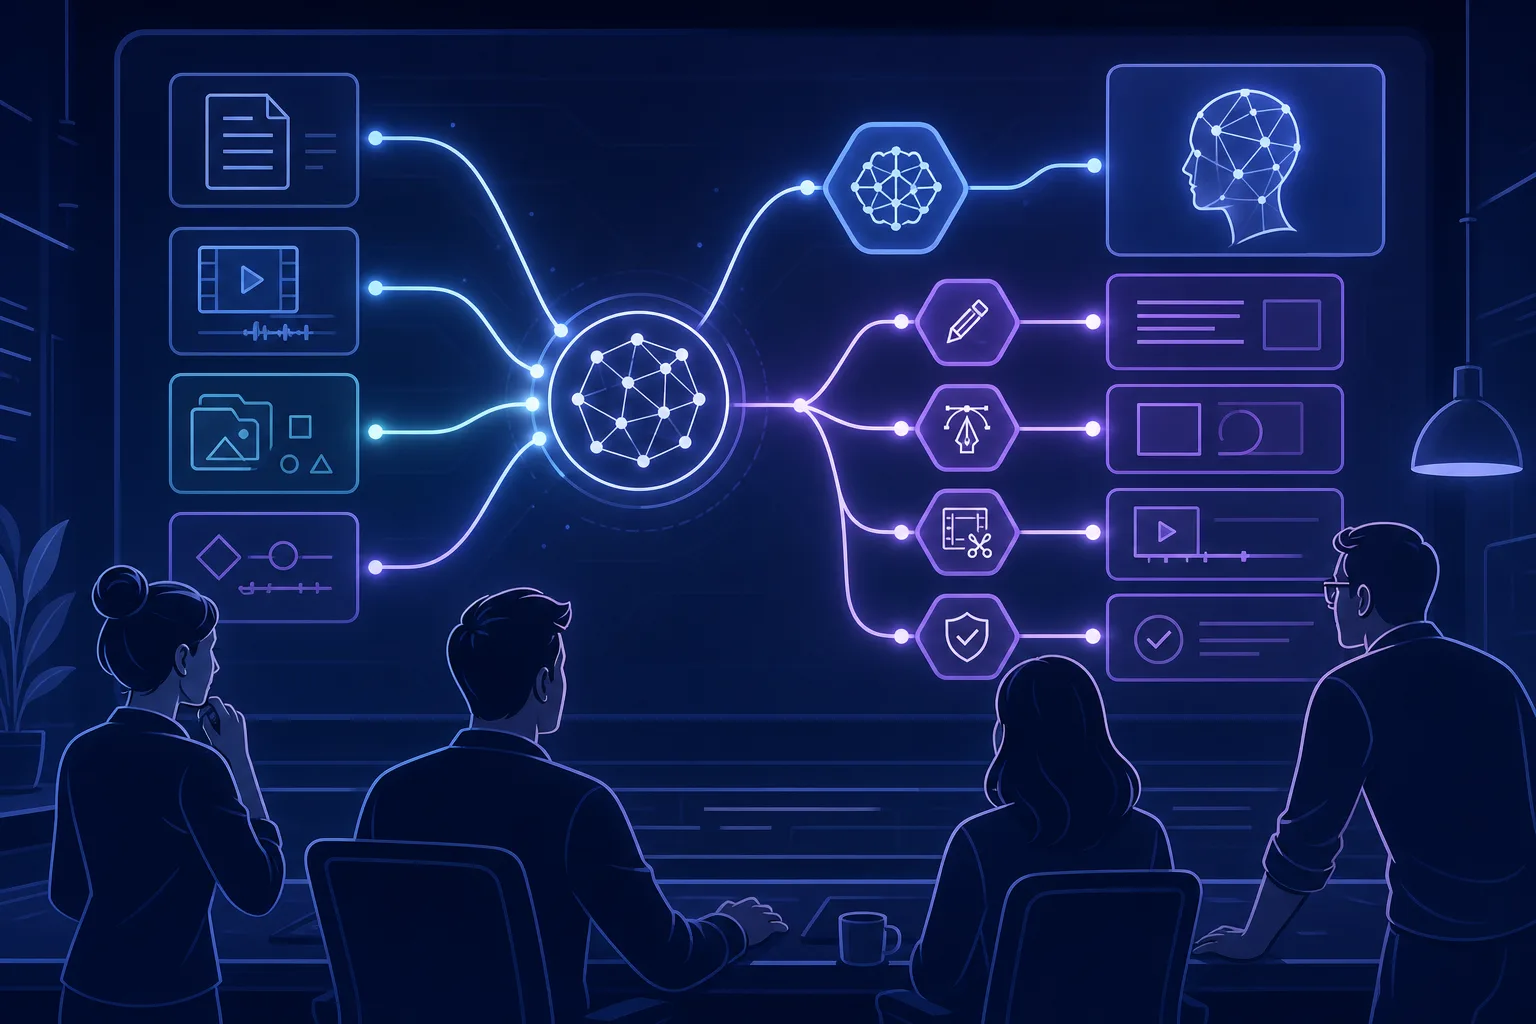
A router works like an air-traffic controller for generative AI. It examines signals such as task type, complexity, context length, domain, and tool requirements, then selects a model according to predefined rules or learned preferences. A simple request might go to a small, economical model, while an ambiguous campaign brief is reserved for a more capable one.
Routing can improve efficiency, resilience, and task fit. It can also introduce hidden decisions, inconsistent outputs, extra latency, and another system that must be monitored. The right answer therefore depends less on how many models a team can access than on whether its creative work is varied enough to justify orchestration.
What the Architecture Changes
A single-model workflow is straightforward. The team chooses one model, establishes prompt templates and brand instructions, then uses the same system for ideation, drafting, editing, and review. Employees learn one interface and develop intuition about its strengths and weaknesses.
A routed workflow separates the user experience from the model selection. People may still work through one shared interface, but the underlying system can send requests to different models. A unified product does not necessarily mean that one model handles everything; routing can happen invisibly behind the screen.
A typical routed request follows four steps:
- Classify the request. The system identifies whether the user wants ideation, summarization, rewriting, factual extraction, localization, review, or another task.
- Apply constraints. It checks context length, budget, response-time target, approved providers, tool needs, and required output format.
- Select and call a model. A rule, classifier, or scoring system chooses the expected best fit.
- Validate or recover. The workflow may run a quality check, retry the request, or fall back to another model if the first call fails.
An adapter layer can sit between the creative application and model providers. It translates a standard internal request into provider-specific formats and normalizes the responses. Tools such as LiteLLM, Portkey, and Bifrost represent this broader gateway and routing category. The architectural benefit is portability: replacing a model does not have to force changes throughout every connected workflow.
That flexibility has a cost. A team is no longer managing only prompts and outputs. It is also managing classification logic, fallback behavior, provider differences, logs, budgets, and evaluation data.
When One Model Is the Better Creative System
Standardizing on one model is often the stronger choice when consistency matters more than theoretical optimization. This is especially true for teams starting with generative AI or supporting a focused set of use cases.
Consistency is easier to diagnose
Creative quality is subjective. If campaign copy suddenly becomes too formal, a single-model workflow gives the team fewer variables to inspect. The likely causes are the prompt, supplied context, model behavior, or human editing—not an unseen routing decision.
That simplicity helps brand managers establish a recognizable voice. They can build approved examples, terminology lists, prohibited claims, and review procedures around one model’s behavior. No model will follow a style guide perfectly, but stable conditions make variation easier to spot.
Adoption is usually smoother
Writers and marketers build practical knowledge through repetition. They learn which instructions produce useful concepts, how much context to provide, and where the model tends to become generic. Constantly switching models can weaken that intuition because the same prompt may behave differently across systems.
A single model also reduces training and governance overhead. There are fewer provider terms to assess, fewer response formats to normalize, and fewer failure paths to document.
Lower volume may not justify routing
Routing has both technical and organizational overhead. Rules must be written, evaluation sets maintained, and failures investigated. At modest usage levels, the savings from assigning routine work to cheaper models may not repay that effort.
This does not mean every task should receive the most expensive treatment. Teams can still control cost with shorter prompts, reusable context, output limits, caching where appropriate, and separate workflow stages. The important distinction is that optimization happens within one model environment rather than through dynamic model selection.
A single model is particularly sensible when:
- Most requests belong to one or two predictable task types.
- A tightly controlled brand voice is the main success criterion.
- Usage is too low to support meaningful routing experiments.
- The team lacks engineering or platform support.
- Human review is already the dominant quality gate.
When a Router Earns Its Complexity
Routing becomes attractive when a creative operation contains genuinely different kinds of work. A global marketing organization may need campaign ideation, product-description cleanup, research summarization, translation, metadata tagging, policy screening, and executive review. Treating all of those requests as equivalent can waste money or compromise quality.
Match model capacity to task difficulty
Routine classification, safety filtering, short acknowledgments, and structured extraction often do not need a frontier model. Vendor estimates suggest that smaller models may cost five to ten times less per token for suitable tasks, although teams should validate that claim against their own contracts, prompts, and output volumes.
The valuable principle is not “always use the cheapest model.” It is use the least costly model that reliably clears the quality threshold. A weak product claim remains expensive after legal review, correction, and delayed publication.
For example, a campaign workflow might route:
- Asset tagging and brief classification to a small model.
- Headline variations to a fast general-purpose model.
- High-stakes positioning concepts to a more capable model.
- Final brand and claim review to a separately configured evaluator.
- Failed or uncertain requests to a designated fallback.
This pattern can also divide work by stage. One model plans, another drafts, and a third reviews. The handoffs need explicit schemas and instructions; otherwise, each stage may reinterpret the brief and gradually dilute the original strategy.
Improve resilience without duplicating applications
A router can redirect work when a preferred model is unavailable, rate-limited, or unsuitable for a particular context length. Centralizing access, fallbacks, cost controls, and monitoring also prevents every creative application from building its own integration.
Fallbacks should not be treated as interchangeable replacements. A backup model may require a different prompt, produce a different tone, or support different tools. Teams should test fallback outputs before an outage rather than discovering those differences during one.
Accept the routing tax
Routing adds time before generation starts. Published engineering estimates put simple rules below one millisecond, embedding-based decisions around several milliseconds, and heavier semantic classification around 50–100 milliseconds. Those figures are small beside model responses that may take hundreds or thousands of milliseconds, but the routing delay can grow when classification, retries, and multiple review calls are chained together.
Cost claims deserve similar caution. Some vendors report very large aggregate savings based on the assumption that most subtasks can move to smaller models. Those outcomes are possible only when the task mix supports them. A creative department dominated by complex strategy and nuanced copy may have far fewer requests that can be safely downgraded.
Design Routing Around Creative Intent
The most understandable design is often front-door routing. A small language model assigns each prompt to a human-readable task category, and a lookup table selects the model tier, context policy, output budget, and quality gate.
A practical taxonomy for marketing work might include:
| Task category | Example | Likely priority |
|---|---|---|
| Ideation | Develop campaign territories | Originality and strategic range |
| Drafting | Write landing-page copy | Brand fit and persuasion |
| Transformation | Shorten copy for paid social | Constraint compliance and speed |
| Extraction | Pull claims from approved documents | Accuracy and traceability |
| Localization | Adapt a message for a market | Cultural and linguistic judgment |
| Review | Check tone, claims, and formatting | Error detection and consistency |
These categories are more useful than vague labels such as “easy” and “hard.” They allow marketers to inspect a routing decision and override it. They also support different policies: extraction might require low creativity, while ideation may permit wider variation.
Ambiguity is the central risk. “Make this campaign stronger” could mean strategic repositioning, copy editing, visual ideation, or a factual review. A router that confidently guesses may select the wrong model and give the user no explanation.
Good systems therefore include an uncertainty path. They can ask a clarifying question, choose the safer high-capability model, or route the request for human triage. The goal is not perfect automated classification. It is controlled failure when the intent is unclear.
Brand context should remain independent of the selected model. Store approved voice guidance, audience definitions, product facts, legal restrictions, and campaign history in a governed context layer rather than embedding them only in provider-specific prompts. Each route can then receive the same source material, even if its prompt formatting differs.
Evaluate the Workflow, Not the Model Leaderboard
Public benchmarks can narrow a shortlist, but they cannot decide whether a system will produce useful work for a particular brand. Benchmark contamination may inflate results, and narrow tests often miss ambiguous briefs, multi-turn revisions, changing context, and subjective creative preferences.
Build an evaluation set from representative work instead. Remove confidential material where necessary, but preserve the characteristics that make the task difficult: incomplete briefs, competing constraints, regulated claims, unusual tone, and revision history.
Score both the output and the operation:
- Creative quality: Is the idea distinctive, relevant, and usable?
- Brand consistency: Does it follow voice, terminology, and positioning rules?
- Constraint compliance: Did it respect format, length, claims, and audience requirements?
- Human preference: Which output do qualified reviewers choose when model identity is hidden?
- Edit burden: How much work is required before publication?
- Reliability: How often do calls fail, time out, or require a fallback?
- Cost and latency: What does the complete workflow consume, including routing and review?
Compare three conditions where possible: the current human or AI-assisted baseline, the proposed single-model workflow, and the routed workflow. Keep prompts, source material, and reviewers as consistent as practical.
Observability must continue after launch. Monitor cost, latency, errors, route selection, fallback frequency, and quality outcomes. Creative demand changes with campaigns and channels, while models and prices also change. A routing policy that worked during a product launch may be inefficient for routine content maintenance.
Quick Checklist
- Map actual tasks by intent, risk, volume, and required turnaround time.
- Identify where brand consistency matters more than marginal cost savings.
- Build a representative test set that includes ambiguous and difficult briefs.
- Compare one-model and routed workflows using blinded human review.
- Count routing, retries, validation, and human editing in total cost and latency.
- Define fallback behavior and test backup models before production use.
- Schedule regular reviews of routing rules, quality results, and provider changes.
Frequently Asked Questions
Is an AI router itself another language model?
Sometimes. A router may be a set of deterministic rules, an embedding-based classifier, a small language model, or a learned scoring system. Rules are fast and auditable, while model-based classification can handle more varied language but adds cost and uncertainty.
Will using multiple models damage brand consistency?
It can, because models interpret the same style instructions differently. A shared brand-context layer, standardized output schemas, approved examples, and a common final review stage can reduce variation. Teams should still test consistency directly rather than assuming prompts will transfer cleanly.
Should every creative stage use a different model?
No. More stages create more handoffs, latency, and opportunities for context to be lost. Assign separate models only when testing shows that specialization improves a meaningful business or creative outcome.
Can routing include image and other multimodal models?
Yes. The same decision logic can direct image, text, audio, or multimodal requests according to task and constraints. Evaluation must remain medium-specific: visual identity, composition, text rendering, rights policies, and revision control differ from copywriting criteria.
How often should routing rules be reviewed?
There is no universal schedule. Review them when costs, models, campaigns, failure patterns, or quality requirements change, and establish a regular operational review based on usage volume. High-volume workflows generally produce enough evidence to justify more frequent adjustment.
Final Thoughts
In practice, a router should be treated as an operating model, not a fashionable AI feature. Its value comes from matching clearly different tasks to appropriate capabilities. If a team cannot describe those task differences or measure the result, routing is likely to hide complexity rather than remove it.
The strongest default for many creative teams is to begin with one well-governed model. That approach builds prompt discipline, exposes real task patterns, and creates the evaluation data needed for a later routing decision. Multi-model architecture becomes persuasive when recurring workload—not vendor enthusiasm—shows that some requests are being over-served while others need specialist treatment.
The bigger picture is that model selection should become less visible to creators but more accountable to operators. People should not have to study provider menus before writing a brief. Yet brand managers need to know why a route was chosen, what it cost, whether it failed, and how the output compared with alternatives.
The best creative workflow is therefore not the one with the most models. It is the simplest system that reliably protects brand quality, makes sensible use of resources, and leaves room for human judgment where taste and responsibility cannot be automated away.
Sources
- Intelligent LLM Routing: How Multi-Model AI Cuts Costs by ...
- Multi-Model Routing: Optimize AI Tasks Efficiently
- AI Model Routing Explained: Cut LLM Costs (2026)
- Multi-Model Agent Orchestration: Routing, Fallback, and Model Selection Strategies | Zylos Research
- Multi-Model Architecture | Model Routing & Orchestration
- Optimize AI Architecture with Model Routing and ...
- How to Use a Multi-Model AI Coding Workflow: Fable for Planning, Composer for Execution, GPT for Review | MindStudio
- How AI Model Routing Works: Why One Model Isn't Enough Anymore | Dapto Blog
- Why One AI Model Isn't Enough for Modern Content Teams
- AI Model Routers Compared: Bifrost, LiteLLM, Portkey & More | MindStudio
- Evaluating Small Language Models for Front-Door Routing:A Harmonized Benchmark and Synthetic-Traffic Experiment
- 25 AI benchmarks: examples of AI models evaluation
Ready to Get Started?
Explore production-ready 3D models for your next project. Browse the 3D model catalog to download assets you can use right away.
Turn this workflow into real deliverables
Browse production-ready 3D models for your next project, then step into 3d modeling if you need a custom build.